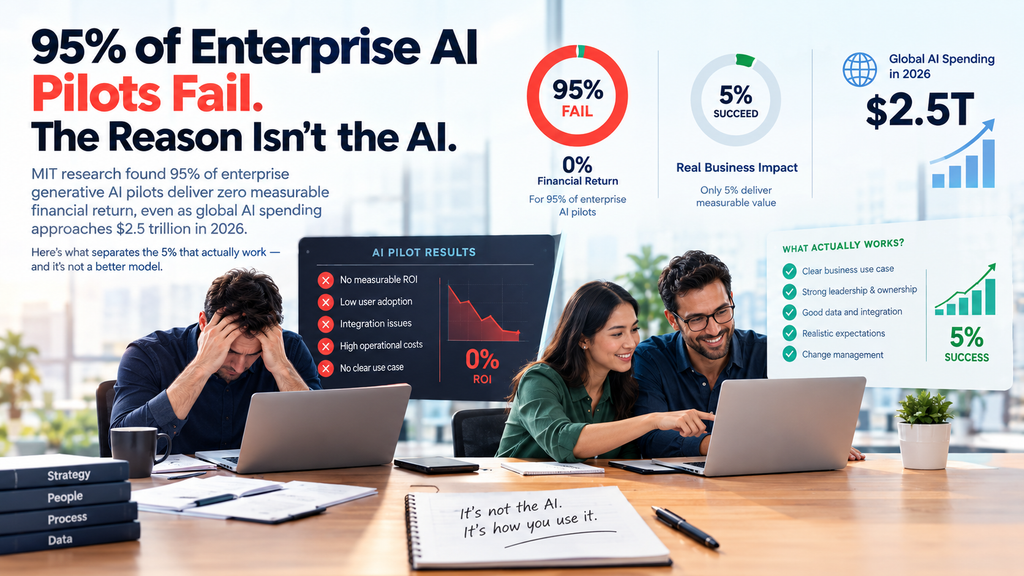
If you sell AI solutions to companies or are considering how to implement AI within your own organization, you should consider this statistic: This year, an MIT study revealed that 95% of enterprise generative AI pilots have no discernible effect on profit or loss. rewards that are not unsatisfactory.
not returns that are below target. Nothing. Since then, a number of independent studies have come to similar conclusions. According to one industry survey, 42% of businesses gave up on the majority of their AI initiatives in 2025, which is more than twice as high as the abandonment rate from the previous year. Another analysis of failure causes revealed that the failure rate of AI projects was about twice that of regular IT projects.
In the meantime, it is anticipated that this year’s global AI spending would be close to $2.5 trillion. The real narrative of enterprise AI at the moment is that gap, trillions of dollars spent, a 95% failure rate on quantitative return, and it’s easier to comprehend than practically any single model release.
What the number actually measures, and what it doesn’t
It’s important to define “95% fail” precisely before making any judgements because it’s more exact than it might seem. It doesn’t measure pilots that have no discernible effect on profit and loss, nor does it measure technically flawed or unpopular systems.
Regardless of whether the underlying tool truly benefited anyone, a pilot that was started without a baseline to compare against lands in that 95% because there was never a means to verify. The majority of discussion of this figure ignores this distinction, which is crucial for how the fix appears.
It’s also important to identify what the data indicates isn’t the issue because it goes against what most businesses assume when a pilot does poorly. The demonstrations are successful. Positive comments are given to internal reviews. Using solutions like ChatGPT and Copilot, individual employees do actually get measurably faster at particular jobs; this productivity improvement is real and well-documented.
The organisational level is where the failure manifests itself most clearly: individuals becoming faster does not consistently translate into the company becoming more profitable, and that gap is where nearly the whole narrative resides.
The actual pattern separating the 5% from the 95%
The same few structural factors consistently surface in this research, and none of them are related to model capability:
Unclear or non-existent success indicators. Over 60% of AI initiatives were approved based on a projected ROI that was never measured after launch, according to a startling report from 2026. No matter how well the tool worked, “did this work” isn’t answerable afterward if no one specified what success looked like before the pilot began.
The AI layer is supported by weak data foundations. Several investigations have shown that the usual enterprise AI deployment pattern looks the same everywhere: take a capable model, construct a system prompt, aim it loosely at a document library, and ship it as a “AI assistant.” Instead of using a general-purpose chatbot directed at a file sharing, the organisations that are truly collecting return avoid taking that shortcut by connecting their AI systems to actual, organised institutional data with appropriate access constraints.
According to one investigation, MLOps maturity level was the single most reliable indicator of ROI: on the identical underlying models, ad hoc deployments with no version control or monitoring showed negative median returns, whereas fully regulated, monitored deployments showed highly positive ones.
There is no true integration with the actual work process. It is uncommon for a pilot that resides in a separate tab, requires employees to remember to access it, and isn’t integrated into the workflow where the task already takes place to survive interaction with a busy person’s actual day. Instead of an extra destination vying for users’ attention, the pilots that are effective are those that are integrated into the tool they were already using.
Executive sponsorship faded after the first launch. AI pilots who receive significant funding and attention during the first month before silently losing their champion typically stagnate in the same state as when they were originally launched; they are never reliable enough to be relied upon.
The economics that separate the winners more sharply than people expect
The return on investment isn’t insignificant for the companies that do this properly. According to one estimate, the successful 5% make about $3.70 for every dollar spent; this return increases over time as the underlying agents and workflows get better.
That is not a “pilot working a little better” result; rather, it falls into a very distinct category than the 95% who receive no measurable results at all. The majority of businesses are grouped somewhere in the middle of the gap between those two outcomes, which is not a spectrum.
It’s more akin to a precipice: either you’re on the side that is properly integrated, managed, and structured, or you’re not, and there isn’t much incentive to be halfway there.
Why this matters if you sell to enterprises
This information should change your sales conversation more than your product roadmap if you’re developing an AI product for corporate clients. Unbeknownst to them, a potential customer who enquires about “does your AI work” is frequently asking a question that your product is unable to answer on its own.
This is because the effectiveness of your product largely depends on whether you have developed the workflow integration and data governance that distinguish the 5% from the 95%. Vendors that are successful in this context are increasingly offering the controlled, integrated layer, which includes workflow-native deployment, explicit success baselines, and permissioned access to actual data, rather than just API access to a functional model encased in a chat interface.
If your product is now competing mostly on “which model powers us,” that is a truly helpful repositioning. The majority of clients never needed the model as a distinction. The effort on integration and governance surrounding it is becoming more and more unglamorous.
Why this matters if you’re deploying AI internally
The solution suggested by this research is practical and doesn’t call for improved technology if you’re managing or funding an AI pilot within your own business:
Establish the baseline and success metric prior to launch, not after. You’re already on the 95% side if you can’t sum up what “this pilot worked” and how it was measured.
The AI layer should be placed on top of data access and governance, not the other way around. Almost often, a modest model connected to clean, well-governed data will outperform a capable model connected to dirty, unpermissioned, badly structured data.
Instead of creating the pilot as a place that users must remember to go, incorporate it into the workflow where the task already takes place. Adoption is much more likely to follow convenience than capabilities.
Assign a designated owner who will be responsible for the pilot’s results beyond the launch month. In the postmortem, the majority of the failures linked to organisational follow-through had a missing name.
The honest takeaway
This story’s painful version is also helpful: the AI functions for the most part. Most of the time, the organisations that surround it aren’t yet structured to take advantage of the value it can generate. That’s a fixable, dull structural issue, which is good news because dull structural issues are precisely the kind that are resolved once enough people realise they’re the real issue rather than waiting for a better model to do it for them.
Send this to the owner of your company’s AI pilot if it has been “in progress” for six months and no one has been able to determine whether it is effective. Next week: a template that you may use to see what a decent AI pilot baseline looks like.